AI Image
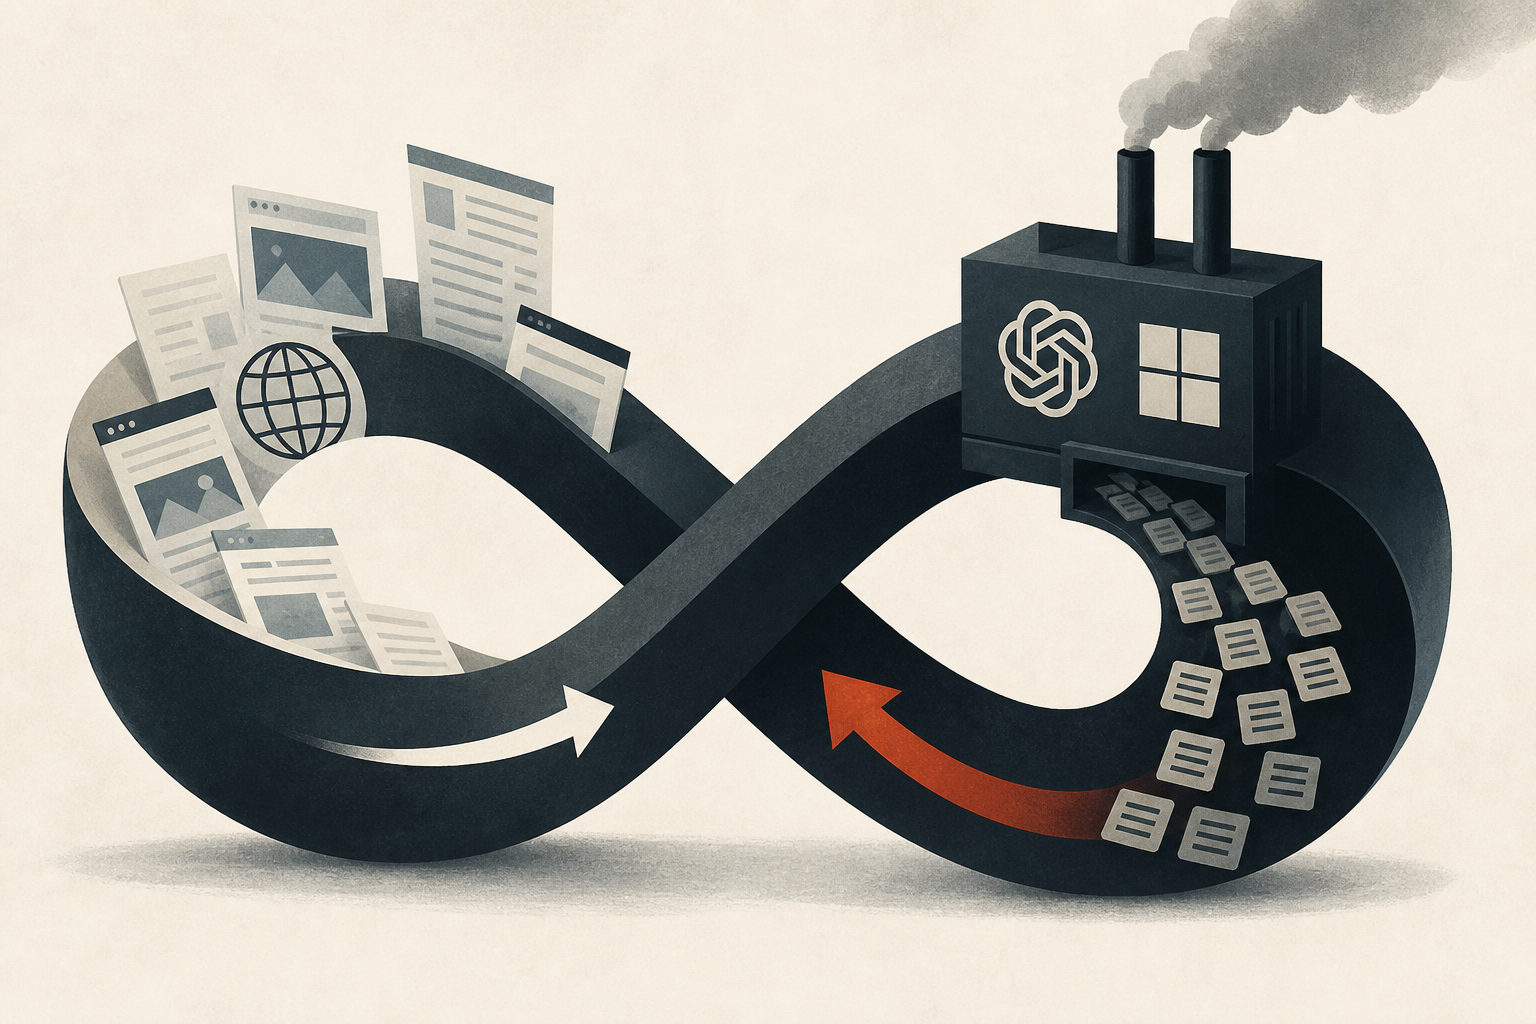
OpenAI and Microsoft knew they were starting a ‘doom loop’ for the web
The Verge • • business
Key Points:
- Recently unsealed court documents reveal that internal communications from OpenAI and Microsoft described their data scraping practices for AI training as the “largest theft of labor in human history” and acknowledged creating a “doom loop” harming both web content providers and their own AI models.
- Microsoft’s Director of Applied Science, Brent Hecht, made many critical statements about AI’s impact on content creators, though Microsoft has distanced itself from his views, calling them individual and theoretical rather than company positions.
- Internal documents show Microsoft and OpenAI recognized that AI chatbots like ChatGPT reduce referral traffic to original news sites by providing direct answers, effectively substituting for the labor of content creators and threatening the economic foundations of publishers.
- Despite public claims about respecting paywalled content, OpenAI admitted internally to not actively filtering such material from training data, and acknowledged that GPT-4 memorizes and regurgitates copyrighted content verbatim.
- The filings suggest that both companies prioritized commercial gains despite knowing their AI strategies would damage the publishing industry, harm content creators’ livelihoods, and undermine the very data supply chains their AI depends on.


